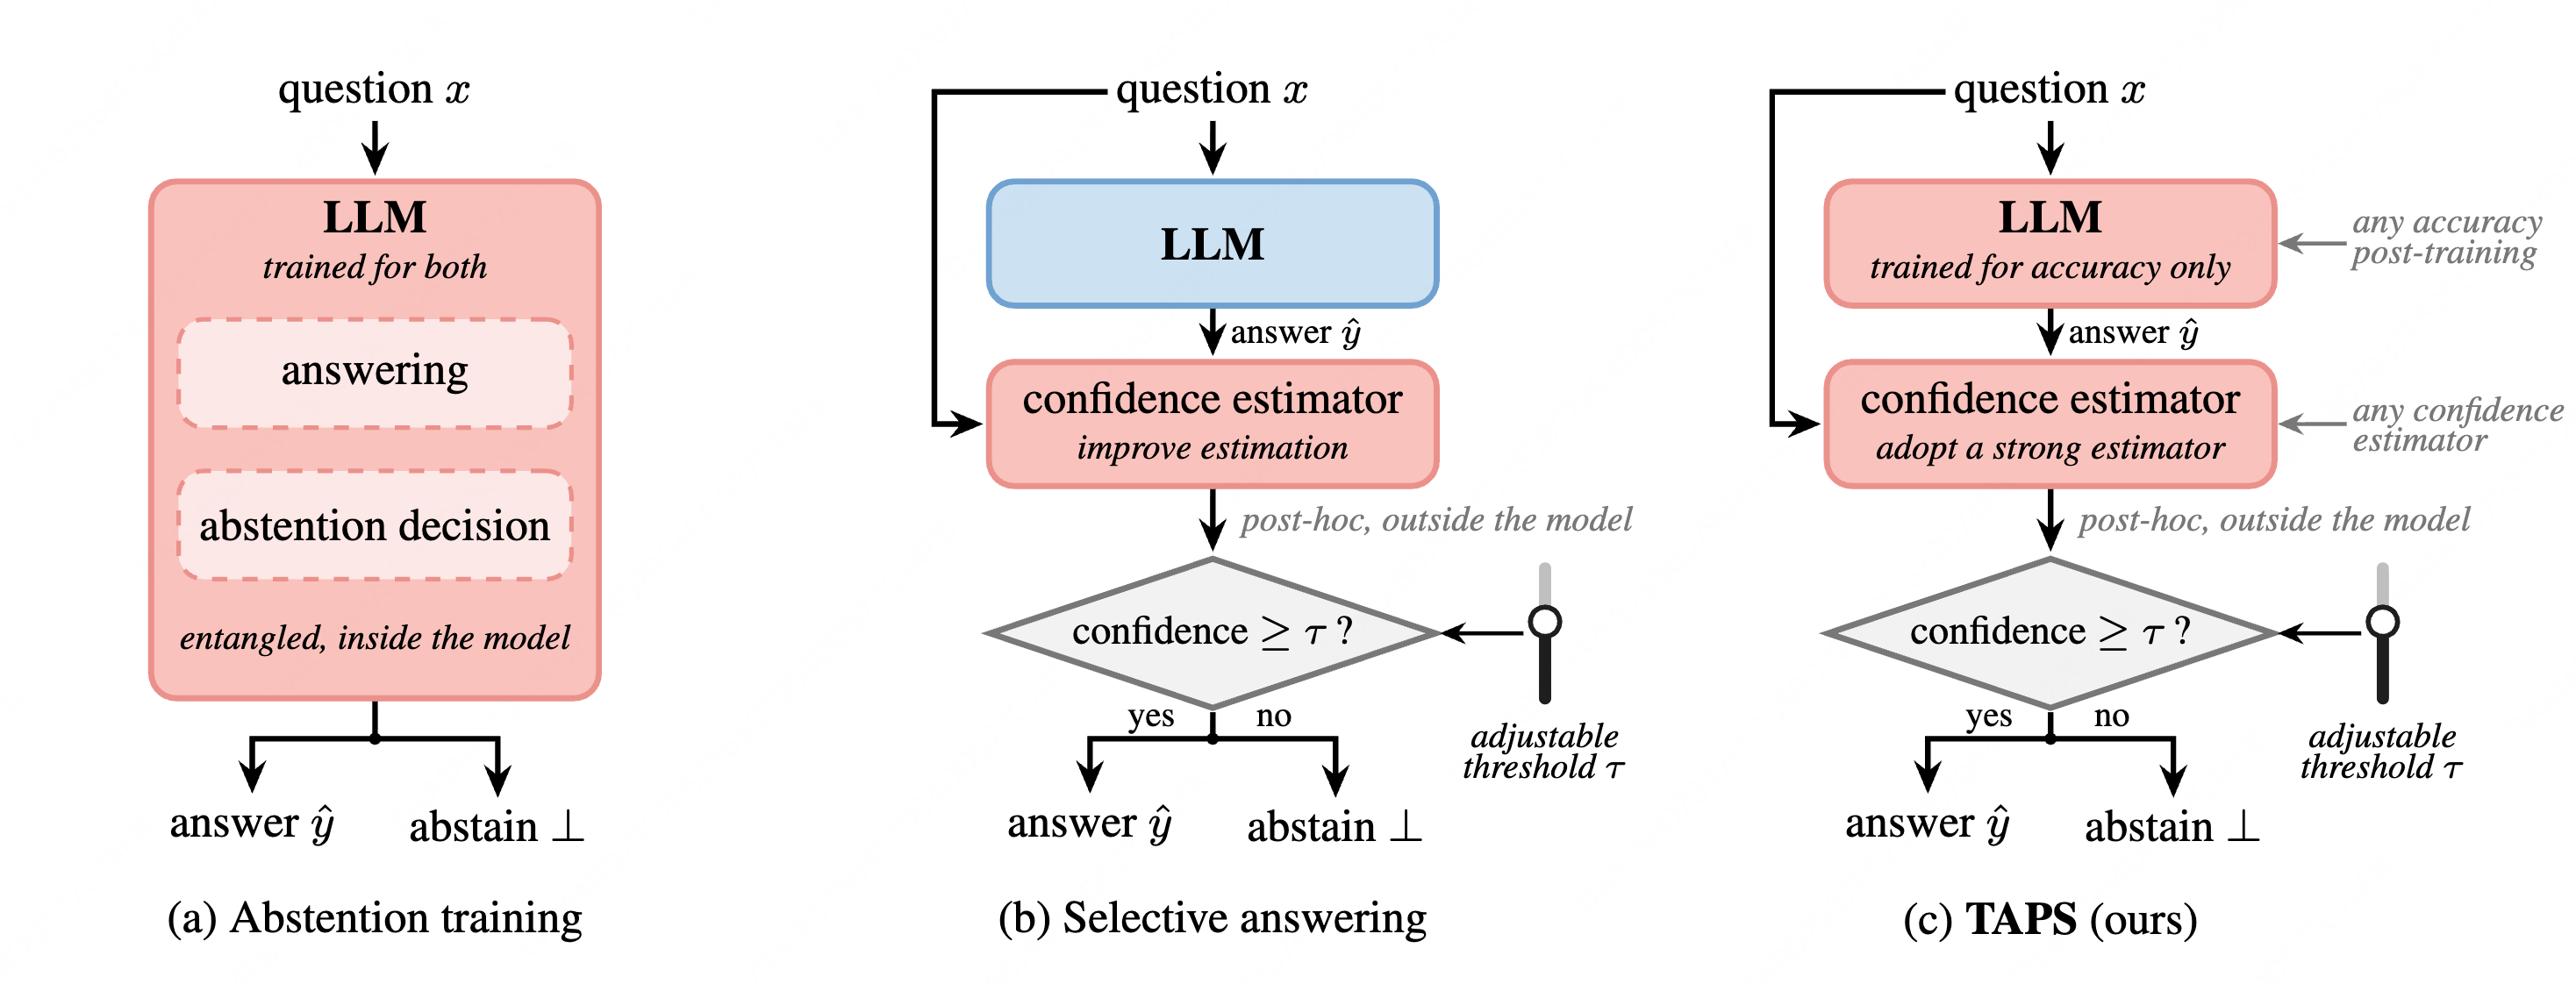
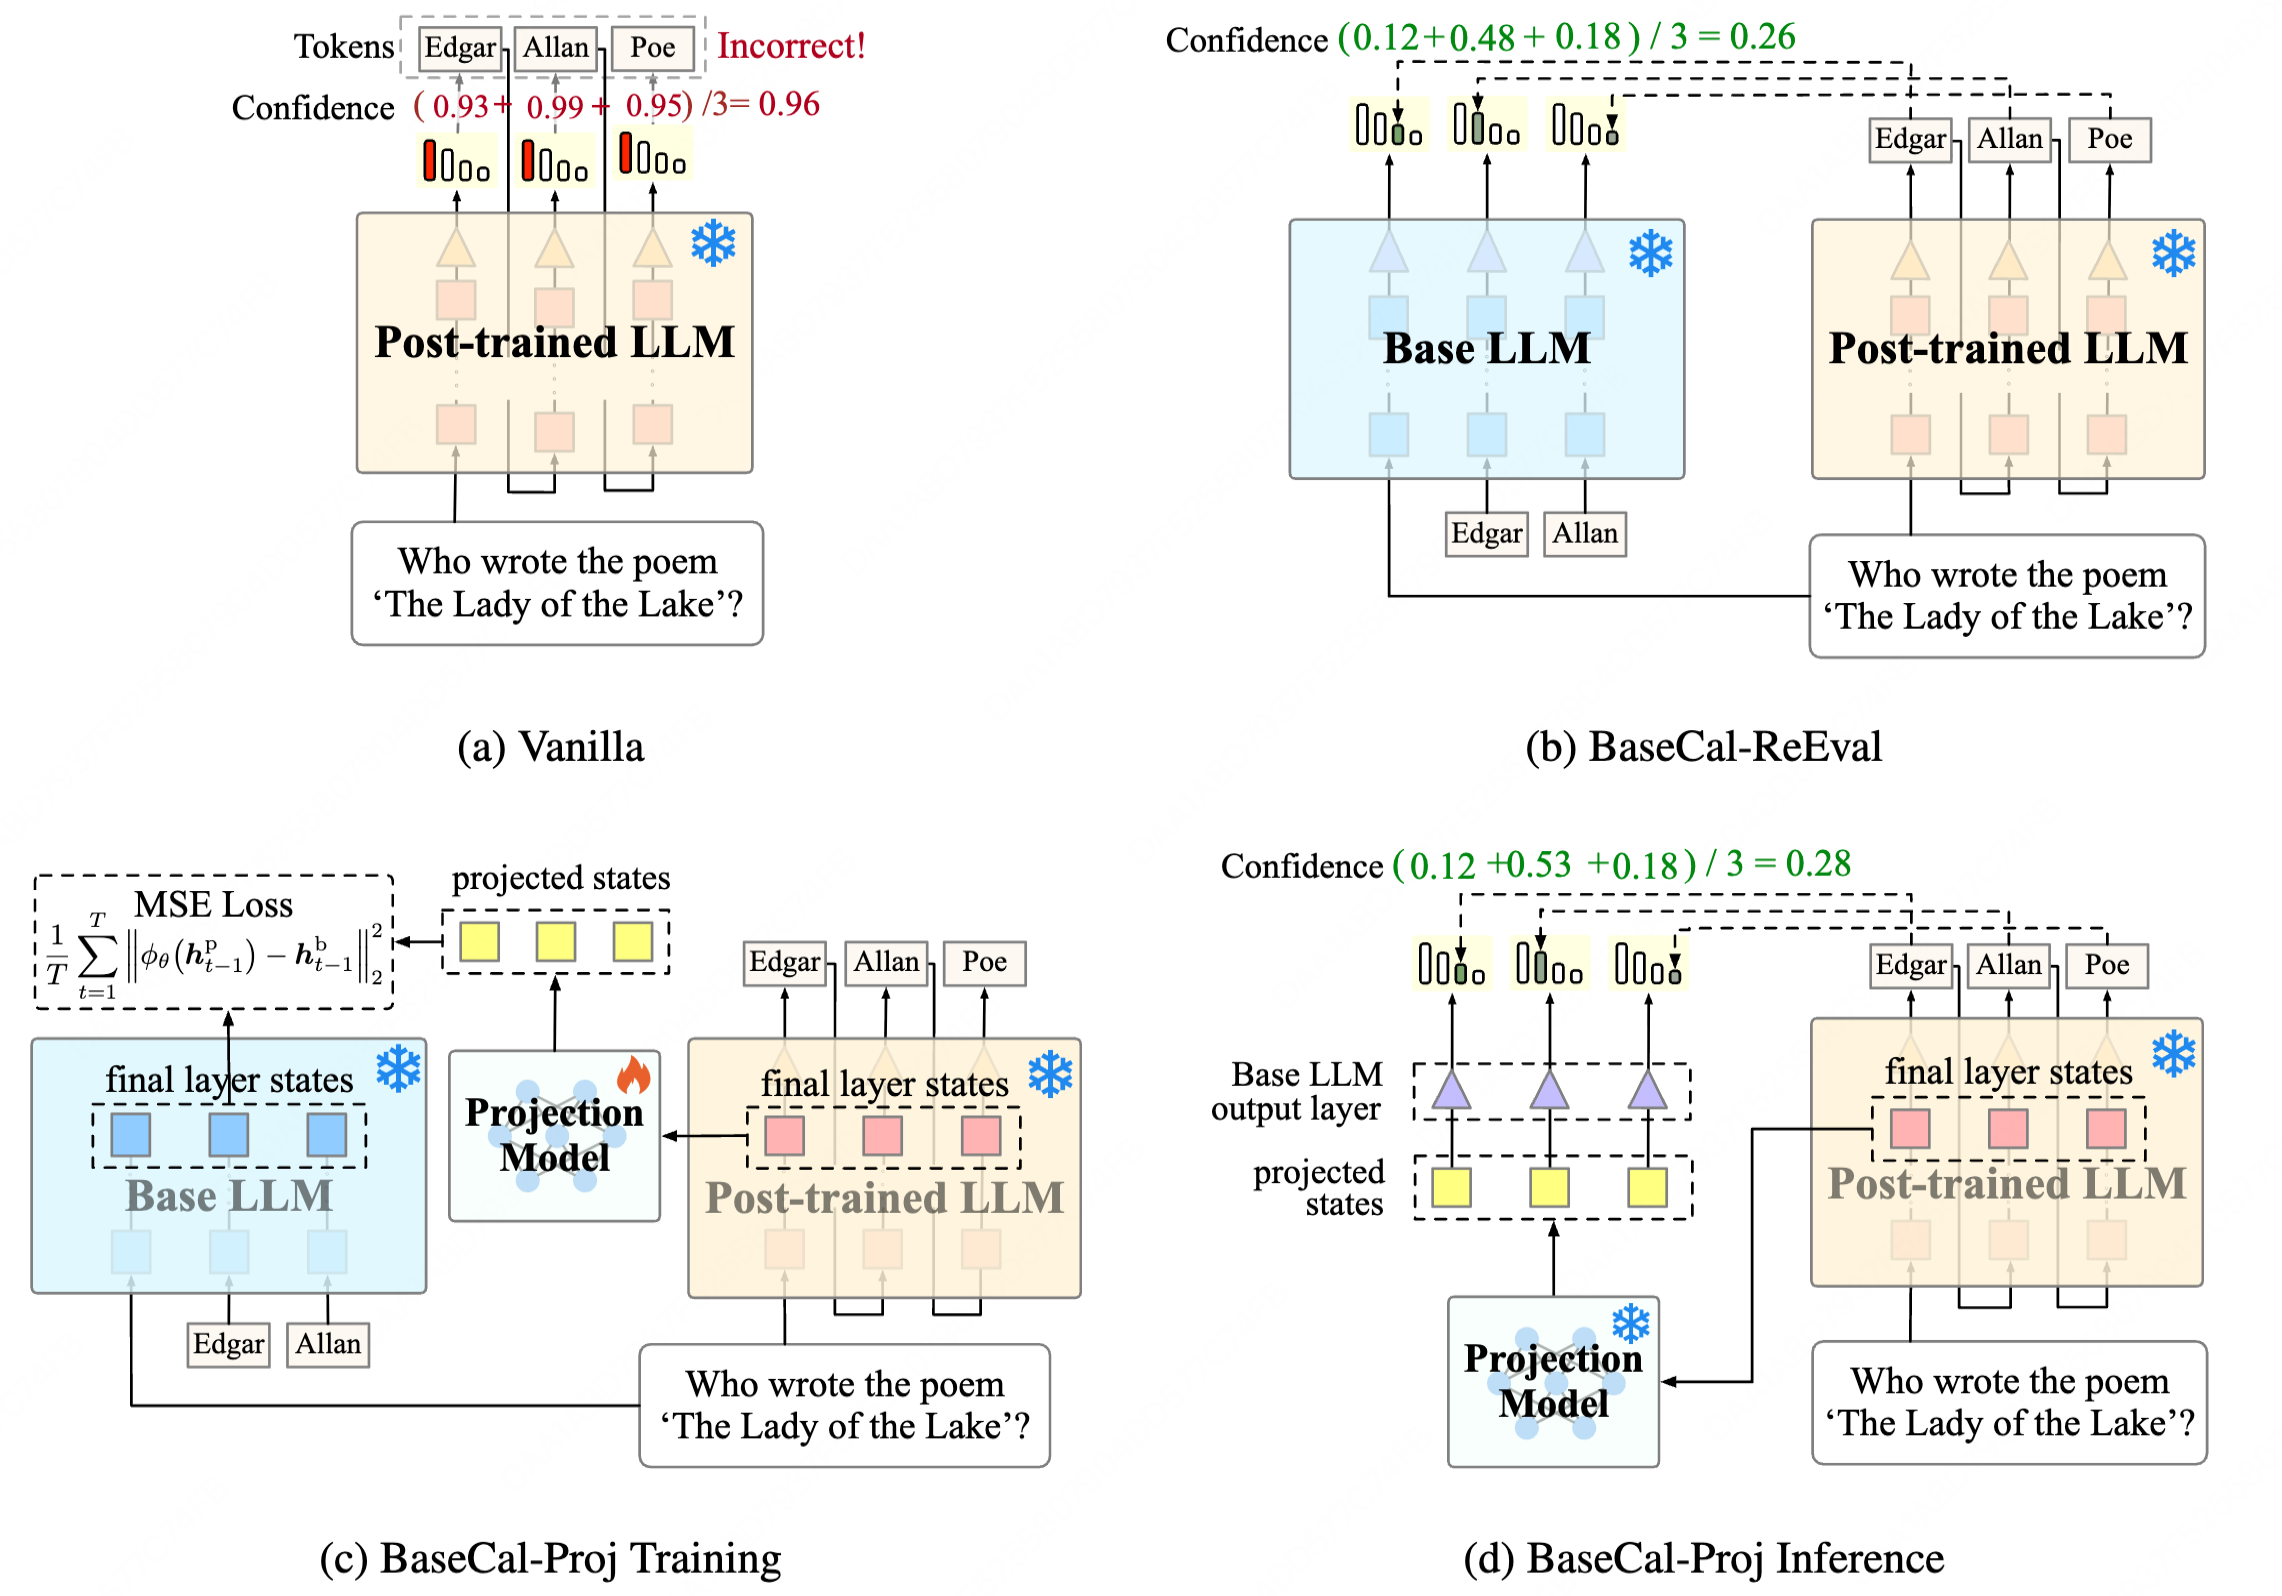
Preprints arXiv Preprint Strong yet Controllable LLM Abstention without Learning to Abstain Junwei Zhang*, Yifei Wang*, Wanli Yang, and 6 more authors (* Equal contribution) arXiv 2026 Paper Project arXiv Preprint Beyond Reasoning: Reinforcement Learning Unlocks Parametric Knowledge in LLMs Wanli Yang, Hongyu Zang, Junwei Zhang, and 5 more authors arXiv 2026 Paper 2026 ACL 2026 BaseCal: Unsupervised Confidence Calibration via Base Model Signals Hexiang Tan, Wanli Yang, Junwei Zhang, and 7 more authors In Proceedings of the 64th Annual Meeting of the Association for Computational Linguistics, 2026 Paper Code